Working GRPO by Hand: The Arithmetic Behind DeepSeek-R1's Aha Moment
Barakaeli Lawuo, Oct 4, 2026
Partway through training DeepSeek-R1-Zero, its authors caught the model doing something nobody had asked for. It was working through an equation with nested square roots, squaring both sides, when it wrote: "Wait, wait. Wait. That's an aha moment I can flag here." Then it went back and re-checked the steps it had already taken. The team printed the transcript as Table 2 of the DeepSeek-R1 paper and called it "an aha moment for us" as well.1
What makes the moment strange is how little the model was told. R1-Zero started from DeepSeek-V3-Base with no supervised fine-tuning first. Its reward came from rules: one part checked whether the final answer was correct, the other whether the reasoning sat inside the right tags.1 Nobody graded individual steps, and no demonstrations showed what reflection looks like. Even so, its average pass@1 on the AIME 2024 math competition rose from 15.6% to 77.9% during training, and 86.7% with majority voting.1 Its responses grew longer as training went on. The word "wait" was nearly absent early, showed up now and then between steps 4,000 and 7,000, and spiked after step 8,000.1
The algorithm doing the learning is GRPO, Group Relative Policy Optimization, which DeepSeek introduced a year earlier in the DeepSeekMath paper.2 Its central step is small enough to do on paper, so that is where this post starts. The full objective and the comparison with PPO follow from it.
Eight attempts at one problem, graded by a script
Take one math question . GRPO asks the current model, called the policy, to answer it several times. The group size is . DeepSeekMath sampled 64 answers per question and R1-Zero sampled 16.2,1 To keep the arithmetic readable, use .
A script checks each final answer against the known solution and returns 1 for correct, 0 for wrong. (R1-Zero also added a format reward with the same weight.1 It is left out here to keep the numbers clean.) Suppose answers 1, 4, and 7 are right and the other five are wrong. The rewards are .
GRPO's rule for turning rewards into a learning signal is to subtract the group mean and divide by the group standard deviation.2 Written out for this group:
The number is called the advantage: how much better an answer did than what was expected. Here "expected" means the average of the model's own attempts at the same question. A quick check: three answers at +1.29 and five at −0.77 add up to about zero. That always happens, because subtracting the mean centers the group. Every update pushes some answers up and others down by matching amounts.
The advantage belongs to the whole answer, not to one step. With a reward only at the end, DeepSeekMath sets the advantage of every token in answer to that answer's normalized reward.2 So each token of answer 1, including any lucky guesses along the way, gets +1.29. Each token of answer 2 gets −0.77. With outcome rewards like these, GRPO has no way to know which line of a wrong answer went bad.
An easy question and a hopeless one
Now suppose a different question where seven of the eight answers are right. The mean is 0.875 and the standard deviation is about 0.331. Each correct answer gets a small advantage of about +0.38. The one wrong answer gets about −2.65, a hard push down. The general pattern for pass/fail rewards falls out of the same arithmetic. If a fraction of the group is correct:
A rare success on a hard question gets a large positive advantage, and a rare failure on an easy one gets a large negative one. It is grading on a curve, one question at a time.
The last case is the degenerate one. If all eight answers are right, or all eight are wrong, every reward equals the mean, the numerator is zero for everyone, and the question contributes no gradient at all. The DAPO paper points out that this gets worse as training goes on: the number of questions the model always solves keeps rising, so fewer questions in each batch carry any signal. DAPO's fix is to over-sample and drop questions whose group accuracy is exactly 1 or 0 until the batch is full.6
From one group to the loss the optimizer sees
Knowing that answer 1 should become more likely does not say how far to move. The full GRPO objective handles that, and it borrows most of its parts from PPO. Five terms first:
- Old policy
- A frozen snapshot of the model taken just before an update. It is the model that actually generated the group of answers.
- Probability ratio
- How much more (or less) likely the updated model makes a token than the old policy did. A ratio of 1 means no change.
- Clipping
- Cutting the ratio off at and so one update cannot move the model too far. PPO's paper uses as its example value.3
- Reference policy
- A separate frozen copy of the model that training is kept from drifting too far away from.
- KL divergence
- A measure of how different two probability distributions are. Here it measures how far the policy has moved from the reference.
With those in hand, here is the objective as DeepSeekMath writes it, where is token of answer :2
Read it from the inside out. is the number computed by hand above: +1.29 for every token of answer 1. Multiplying by the ratio means the objective goes up when the model makes those tokens more likely. The min and the clip stop the incentive at : once answer 1's tokens are, say, 20% more likely than under the old policy, pushing further earns nothing. For answer 2, with a negative advantage, the same trick caps how hard its tokens get pushed down. PPO's authors describe this as a pessimistic bound: the objective ignores changes that would make it look better and keeps changes that make it look worse.3
The two averages matter more than they look. The inner averages over the tokens of one answer, and the outer averages over the answers in the group. That inner average will come back later.
The last term keeps the model near the reference policy. DeepSeekMath estimates it per token with a form that is guaranteed to be positive:2
The actual settings were modest. For DeepSeekMath-RL 7B the policy learning rate was 1e-6, the KL coefficient was 0.04, answers were capped at 1,024 tokens, and the policy got a single update after each round of sampling.2 R1-Zero used a learning rate of 3e-6, a much smaller KL coefficient of 0.001, and 32 questions per step with 16 answers each, a batch of 512. Its maximum answer length was 32,768 tokens until step 8,200 and 65,536 after. The paper says both accuracy and response length jumped at that step. Training ran for 10,400 steps, and every 400 steps the reference model was replaced with the latest policy.1 The R1 paper also writes the ratio over the whole answer, , rather than token by token.1
What PPO needs that GRPO throws away
The clipped ratio came from PPO. What GRPO changed is where the advantage comes from. In standard PPO for language models, the advantage of each token is estimated with Generalized Advantage Estimation (GAE), which depends on a learned value function: a second network that looks at a partial answer and predicts the reward the rest of it will earn.2,3 GAE combines one-step errors of that prediction,
where trades bias against variance. At the estimate stays unbiased however wrong is, but it has high variance. At it has much lower variance but is biased unless is accurate.4 The value network is trained alongside the policy with a squared-error loss.3
DeepSeekMath gives two reasons for dropping it. The first is cost: the value function "is typically another model of comparable size as the policy model," which brings "a substantial memory and computational burden." The second is that the reward usually arrives only at the last token, which makes it hard to train a value function that is accurate at every token.2 GRPO replaces the learned prediction with the average reward of other answers to the same question, which is exactly the 0.375 computed above.2 The authors also note that comparing answers to the same question fits the way reward models are trained, since those are usually trained on comparisons between outputs for one question.2
The R1 paper adds a reason specific to long reasoning. When a model reflects and revises, an early part of the answer may be contradicted later, so predicting the final reward from a partial answer gets even less feasible.1 It also points to a difference in the KL term. PPO usually adds a per-token KL penalty into the reward, and since RL maximizes cumulative reward, this penalizes cumulative KL. That may implicitly penalize longer responses and keep them from growing. GRPO puts the KL term in the loss instead.1
The same appendix runs PPO and GRPO against each other on the MATH benchmark with DeepSeek-Coder-V2-Lite, a mixture-of-experts model with 16B parameters and 2.4B active. With GAE's at 0.95, which the paper calls the default in most open-source PPO code, PPO did considerably worse than GRPO. Tuned to , PPO came close to GRPO.1 The authors' conclusion is measured: PPO can match GRPO when tuned, but tuning costs compute, and the value model adds memory and compute on top, so GRPO is the more practical choice for large models on limited resources.1
What a 7B model gained, and what it did not
GRPO's first test was DeepSeekMath-Instruct 7B, trained further on about 144K chain-of-thought questions related to GSM8K and MATH.2 It improved on every benchmark reported, including Chinese math sets that were not in the RL data.2
The same paper then asked what RL had actually changed. It measured two things for different numbers of samples : Pass@K, whether any of answers is right, and Maj@K, whether the majority vote of answers is right. RL raised Maj@K but not Pass@K. The authors' reading is that RL made the output distribution more robust, boosting correct answers that were already among the model's top candidates, "rather than the enhancement of fundamental capabilities."2 That fits the arithmetic: GRPO can only reinforce a correct answer the model has already sampled. A question the model never gets right gives an all-zero group and no signal.
Later papers took both averages back out
In 2025, Liu and colleagues argued that the two normalizations in GRPO each add a bias.5 Their figure shows both at once.
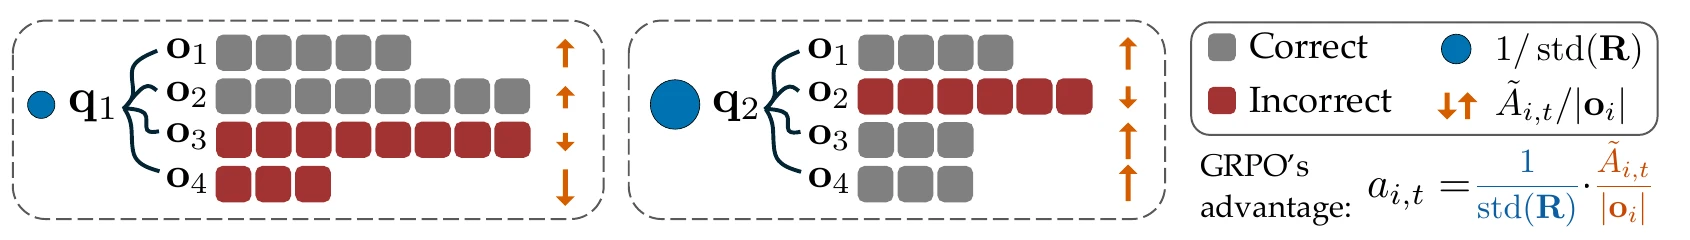
The first is a question-level difficulty bias, caused by dividing by the standard deviation. Questions where rewards are almost all 1 or all 0 have a small standard deviation, so they get more weight in the update.5 The seven-out-of-eight example shows it: the lone wrong answer got −2.65, over three times the −0.77 from the three-out-of-eight group, only because the group agreed more. The authors note that advantage normalization is a common RL trick, but it is usually done across a whole batch, not per question.5
The second is a response-level length bias, from the average. A correct answer's advantage is spread over its tokens, so short correct answers get bigger per-token updates. A wrong answer's penalty is spread the same way, so long wrong answers get penalized less, and the policy drifts toward longer responses among the wrong ones.5 The authors say this bias may explain part of the length growth seen in R1-Zero-style training, and they found the same length normalization in several popular open-source PPO implementations.5 Their fix, Dr. GRPO, removes both the and the standard deviation terms, leaving the plain difference .5 Using it in a minimal recipe, they report 43.3% on AIME 2024 with a 7B base model.5
The same paper also re-examined the aha moment. Running DeepSeek-V3-Base, the model R1-Zero started from, on 500 MATH questions with the R1 template, they found it already produced a fair amount of self-reflection, including words like "Aha" and "wait." In R1-Zero's own answers to those questions, self-reflection was more frequent, but it was not positively correlated with higher accuracy.5 The R1 paper itself reports a 5- to 7-fold rise in reflective words during training.1 Both findings can hold together: RL made a behavior the base model already had much more common. Whether that behavior is what raised the AIME score is a separate question, and Liu et al.'s correlation result is a reason not to assume it.
Reproducing R1-Zero with plain GRPO also turned out to be hard. The DAPO team's first GRPO run on Qwen2.5-32B scored 30 points on AIME 2024, well short of the 47 points DeepSeek reported for DeepSeek-R1-Zero-Qwen-32B. They traced the gap to entropy collapse, reward noise, and training instability, and fixed it with four changes, one of them the zero-advantage filter from earlier. The result was 50 points in half the training steps.6 Much of that work, like Dr. GRPO's, comes down to the same few lines computed by hand at the top of this post: a mean, a standard deviation, and what to divide by.
Sources
- DeepSeek-AI, DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning, 2025
- Shao et al., DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models, 2024
- Schulman et al., Proximal Policy Optimization Algorithms, 2017
- Schulman et al., High-Dimensional Continuous Control Using Generalized Advantage Estimation, 2016
- Liu et al., Understanding R1-Zero-Like Training: A Critical Perspective, 2025
- Yu et al., DAPO: An Open-Source LLM Reinforcement Learning System at Scale, 2025