Two bent rulers: grading text that has no answer key
Barakaeli Lawuo, Jan 14, 2026
In 2021, Elizabeth Clark and five colleagues at the University of Washington and the Allen Institute for AI paid 780 Amazon Mechanical Turk workers US$1.25 each to read five passages of at least 100 words.1 Some passages were written by people. The rest came from GPT-2 or from the 175-billion-parameter GPT-3, in one of three domains: short stories, local news, or recipes. Each worker rated every passage on a four-point scale from "definitely human-written" to "definitely machine-generated." Against GPT-2, the workers picked the right author 57.9% of the time. Against GPT-3, they were right 49.9% of the time. Chance was 50%.1
The team then trained a fresh group of 1,170 workers with three different short lessons and ran the test again. The best lesson lifted accuracy to 55%, and no lesson improved it significantly across all three domains.1 So the people who are supposed to be the gold standard for judging generated text could not tell whether a text was generated at all.
That result is one half of why evaluating open-ended generation is hard. A spam filter or an image classifier has a label to check against, so accuracy and F1 mean something. Gehrmann, Clark and Sellam put the difference plainly in their 2022 survey: when the outputs are natural language, "no equivalent of accuracy or F1-Score exists."4 What we use instead are two rulers. One is an automatic metric that compares the output with a reference text. The other is a group of human raters. This post measures how far each one bends, using the numbers the papers report.
- Open-ended generation
- A task where many different outputs can all be correct, such as writing a summary, a story or a restaurant description. There is no single right string to compare against.
- Reference
- A human-written example output for the same input. Most automatic metrics score a system output by how similar it is to one or more references.4
- Word-overlap metric
- An automatic metric that counts words or word sequences shared between the output and the references. BLEU, ROUGE and METEOR are examples.3
- n-gram
- A run of n consecutive words. "The cat" is a 2-gram (bigram); "on the mat" is a 3-gram.
- Spearman correlation ()
- How well two sets of scores agree on the ranking of the same items, from -1 to 1. Novikova et al. use it to compare metric scores with human ratings.3
- Krippendorff's
- An agreement score between raters that corrects for the agreement they would reach by chance. Zero means no agreement beyond chance.1
The first ruler: counting shared n-grams
BLEU was introduced by Papineni and colleagues at IBM in 2002 for machine translation, and it is the template most word-overlap metrics follow.2 It starts from a simple idea. A good translation shares many words and phrases with good human translations of the same sentence. Plain word matching can be gamed, though. The paper's example candidate is "the the the the the the the," scored against the reference "The cat is on the mat." Every word in the candidate appears in the reference, so ordinary precision is 7/7.2
BLEU fixes this with clipping. Each candidate n-gram is counted at most as many times as it appears in any single reference. "The" appears at most twice in a reference, so the candidate gets credit for 2 of its 7 words, a modified unigram precision of 2/7.2 Written out for n-grams of length over a whole test set:
Precision alone rewards short outputs: a two-word candidate that matches two reference words scores perfectly. So BLEU multiplies by a brevity penalty BP. Let be the total length of the candidate text and the effective reference length, the sum over sentences of the reference length closest to each candidate. The final score takes a weighted geometric mean of the values:2
Read term by term, the equation says: count shared 1-grams through 4-grams, cap the counts so repetition cannot farm points, average the four precisions in log space so one zero drags the whole score down, and cut the score if the output is shorter than the references. Nothing in it looks at meaning. The authors were open about the limits. A footnote says BLEU "only needs to match human judgment when averaged over a test corpus; scores on individual sentences will often vary from human judgments."2 The score also depends on how many references you have. On about 500 sentences, one human translator scored 0.3468 against four references and 0.2571 against two.2
How far the first ruler bends
Jekaterina Novikova and colleagues at Heriot-Watt University tested whether these metrics track human judgment on a generation task rather than translation.3 They took 2,460 outputs from three data-driven systems that turn a meaning representation, such as inform(name=X, pricerange=moderate, type=restaurant), into a sentence about a restaurant or hotel. Crowdworkers rated each output on a 6-point scale for informativeness, naturalness and overall quality, three workers per output. The team then correlated those ratings with 21 automatic metrics, including BLEU, ROUGE, METEOR, CIDEr and a group of grammar-based measures such as readability and parser scores.3
Their summary: "no metric produces an even moderate correlation with human ratings, independently of dataset, system, or aspect of human rating."3 The strongest positive correlation in the whole study, , came from counting the words per sentence, and it was not robust on other datasets. As a sanity check they added a random score between 0 and 1. Its best correlation with humans was .3
The paper found two patterns inside the weak numbers. First, the metrics did better on bad outputs. For utterances with low informativeness ratings, word-based metrics correlated with humans at between 0.3 and 0.5; for average and good ones, the best correlation barely reached 0.2.3 Most outputs were good (79% were rated good for informativeness), so the metrics were weakest exactly where most of the data sat. Second, at the level of whole systems, averaged over all outputs, the word-based metrics followed the same pattern as human informativeness ratings.3 That matches BLEU's own footnote: averaged over many sentences, the ruler is usable. Held against one output, it is not.
One example in the paper shows the failure directly. For the input inform(name=the donatello, hasinternet=yes), a system wrote "well there is a hotel with internet access called the donatello." Humans gave it a median of 6 out of 6 on every scale. BLEU, NIST, LEPOR, CIDEr, ROUGE and METEOR, rescaled to the same 1 to 6 range, all stayed below 1.5, because the sentence used different words from the references.3 The authors also point at the references themselves. The crowdsourced reference "Fifth Floor does not allow childs" is ungrammatical, and a system that copies it would score well on word overlap.3 Word-based metrics, they write, treat human references "as a gold standard, which is correct and complete," and that assumption does not hold for crowdsourced data.3
Learned metrics were built to fix the word-matching part. BERTScore, from Zhang et al., replaces exact matches with cosine similarity between contextual token embeddings from a pretrained model, and matches each token greedily to its most similar partner in the other sentence.5 The paper's motivating case: given the reference "people like foreign cars," BLEU and METEOR score "people like visiting places abroad" above "consumers prefer imported cars."5 BERTScore correlated better with human judgments on translation and captioning. The authors still note that no one configuration of it clearly beats all others.5 The survey adds two cautions. BERT-based metrics remain sensitive to lexical overlap and can be fooled by lexically similar sentences that are not paraphrases, and the name BERTScore refers to a method rather than a model, while the version hashes meant to identify the model are often not reported.4
The second ruler: readers who check the spelling
If the metric bends, the usual answer is to ask people. Novikova's own raters already show the problem. Their agreement, measured by intra-class correlation across all three datasets, was 0.45, which the authors call moderate.3 In one of their examples, a system produced "i but i but i but i but i" and another produced a garbled but partly on-topic sentence. The authors judge the first clearly worse, yet both received a median human score of 1.3
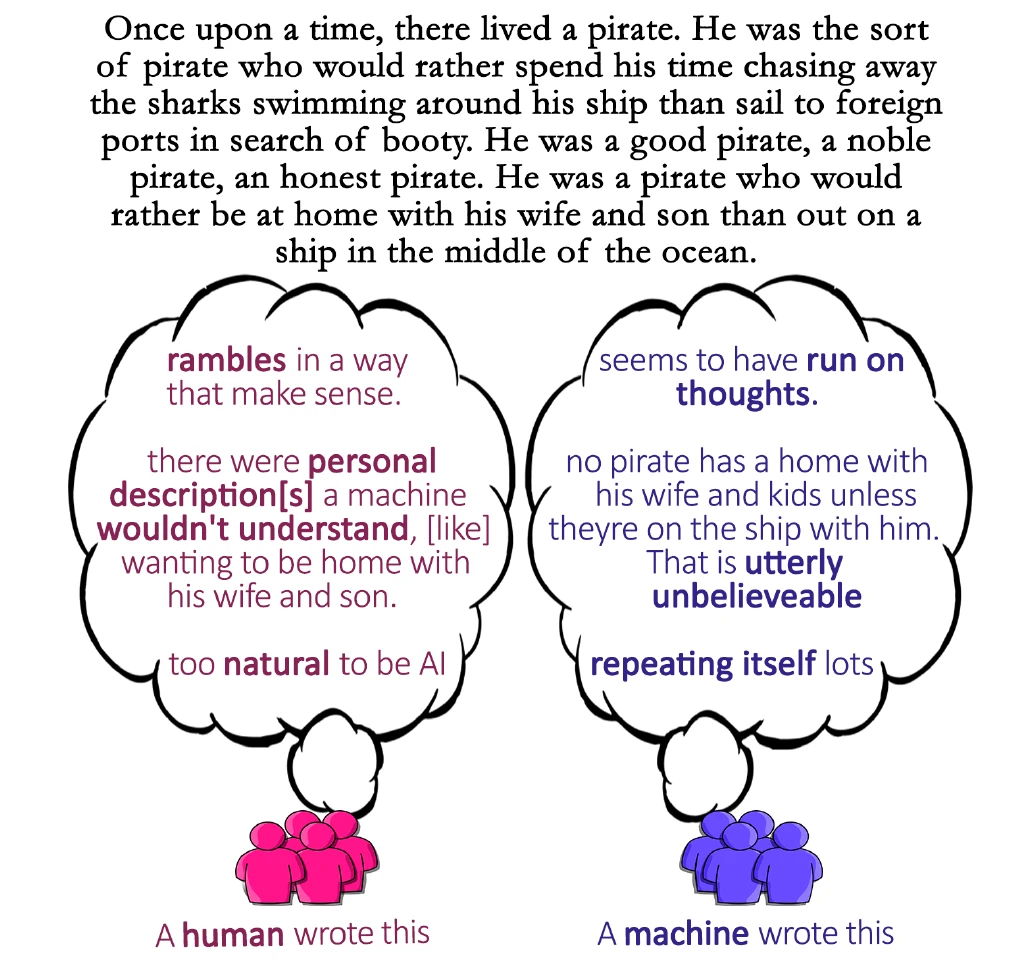
Clark's study measures the human ruler more directly. The GPT-3 texts were produced with three human-written example texts in the prompt and sampled at temperature 0.7.1 Accuracy on GPT-3 text sat at 48% for stories, 51% for news and 50% for recipes. The story domain fell the most, from 62% with GPT-2 to 48% with GPT-3. Agreement between workers was Krippendorff's of 0.00 to 0.05 on the GPT-3 texts, and about two thirds of all GPT-3-condition guesses said "human," even though half the texts were machine-written.1 Workers were not unsure of themselves, either. The share of "definitely" answers stayed roughly constant across conditions.1
The authors annotated 150 of the workers' written explanations. Comments about form outnumbered comments about content nearly two to one (47% of labels against 25%), and the most common topic was spelling, grammar or punctuation, in 45 of the 150.1 Fluency is the one thing GPT-3 had already mastered, so this was the wrong place to look. Workers also used the same feature to reach opposite verdicts. Formality, spelling errors and clarity were each cited as evidence for a human author and for a machine one.1 One worker wrote, "Usually AI has terrible grammer [sic] and messes up."1
Three lessons, 130 readers each
The follow-up study tested whether cheap training could straighten the human ruler. Each method was run with 130 new workers per domain, 1,170 people and 5,850 ratings in all.1
- Instructions ($1.25 per task): the original task text plus a note on what helps (repetition, factual errors) and what misleads (grammar, spelling, style).1
- Examples ($1.75): three practice rounds of the real task, each followed by the correct answer and a short explanation of the clues.1
- Comparison ($2.25): the same practice texts, each paired with a text from the other source written from the same prompt; the worker picks the machine one, then sees the answer.1
Examples training was the only method with a significant overall gain, with a small effect size (Cohen's d = 0.25).1 Most of that came from stories: against no training, mean accuracy rose 0.086 on stories, 0.019 on news and 0.062 on recipes. The authors suggest the examples may have broken the belief that machines cannot write "creative" text.1 Training did change what people looked at. Among workers who had the Examples training, the share of content comments doubled from 24.6% to 50.0%, and form comments fell from 47.1% to 32.5%.1 Agreement did not follow. Krippendorff's stayed at or below 0.11 in every training and domain setting, and higher agreement did not go with higher accuracy.1
Clark et al. also tried a fourth condition in which workers rewrote the generated text to make it more humanlike. They could not run it. Fewer than 30% of recruited workers stayed with the task and more than half of submissions were rejected, and they concluded Mechanical Turk was not a good platform for that kind of task at the price they tested.1 Across both studies, 445 participants (18.6%) were excluded from the results for copied, vague or inconsistent explanations.1
The survey by Gehrmann, Clark and Sellam collects evidence that the human ruler bends in other ways too. It reports that across 165 NLG papers analyzed by Howcroft et al., human evaluations used 204 quality dimensions that mapped to 71 distinct criteria, and that what papers called "fluency" split into 15 different criteria.4 Of 478 evaluation questions in that study, more than half did not define the criterion being rated.4 The survey also cites work showing the same Mechanical Turk evaluation run on different days of the week can produce different results, and that in machine translation, automatic metrics can agree more with expert annotations than crowdworkers do.4 My reading of these findings together: the human score is a measurement with its own error bars, and most papers do not report them.
What the survey asks you to write down
The survey declines to name a single best metric, and says why: "quality is a vastly under-defined property," so a high correlation with one overall human score is the wrong goal.4 Its advice is to measure narrower things and to document how every number was made. For automatic metrics it recommends never relying on a single metric, using at least one entailment or question-answering metric alongside a learned similarity metric such as BLEURT, and documenting tokenization whenever lexical metrics are run on non-English text.4 For human evaluation it asks for effect size estimates, power analysis, significance tests and a check of result validity, a stated rater qualification, and documented instructions, and for model outputs and human annotations to be released so others can re-score them later.4 Clark et al. make a matching request of their own: publish the instructions and training given to evaluators, and ask evaluators why they made each judgment.1
The survey then checked 66 papers from ACL, INLG and EMNLP 2021 against those recommendations. The average paper followed 27.3% of them.4 Of the 48 papers where it applied, none estimated an effect size or ran a power analysis, and 12 ran significance tests on their human results. One of 66 released its model outputs on the validation set, and one of 48 released its human evaluation annotations. Only 29% discussed the limitations of their own method.4 Most chose the "typical" 100 items for human evaluation without estimating how many they needed.4
The limitation the survey names for itself
Both rulers in this post are intrinsic: they grade the text by itself, by overlap with a reference or by a reader's rating. The survey states that this is its own gap. "A limitation of this work, and evaluation in general, is the focus on intrinsic evaluations and the lack of extrinsic evaluation," meaning measurement of whether the text does its job for the people who use it.4 Its example is a general-purpose summarizer run on a newspaper opinion column. Such a system will likely not write "Author X states that Y" and will instead present opinions such as "I don't like math" or "Jollof Rice is tasty" as facts. The authors write that this is a limitation of NLG models "which we are unable to capture using standardized benchmarks alongside intrinsic evaluations."4 On the evidence above, a fluent summary like that could score well on both rulers.
Sources
- Clark, August, Serrano, Haduong, Gururangan, and Smith, All That's 'Human' Is Not Gold: Evaluating Human Evaluation of Generated Text, ACL 2021
- Papineni, Roukos, Ward, and Zhu, BLEU: a Method for Automatic Evaluation of Machine Translation, ACL 2002
- Novikova, Dušek, Cercas Curry, and Rieser, Why We Need New Evaluation Metrics for NLG, EMNLP 2017
- Gehrmann, Clark, and Sellam, Repairing the Cracked Foundation: A Survey of Obstacles in Evaluation Practices for Generated Text, 2022
- Zhang, Kishore, Wu, Weinberger, and Artzi, BERTScore: Evaluating Text Generation with BERT, ICLR 2020